 Otto
AI Second Brain for Founders: Two Minutes to Test What It Remembers
AI Second Brain for Founders: Two Minutes to Test What It Remembers

An AI second brain is a persistent, context-first memory layer that lets an assistant remember your decisions and surface what to focus on today. The payoff is clear morning priorities and far fewer repeated explanations across tools. Below you get the architecture, an afternoon quickstart, privacy controls, and workflow templates built for founders and operators.
TL;DR:
- Start with an operating manual and dated decisions with reasons; prioritize clean metadata, timestamps, and source links over importing a large document archive.
- Test five known facts in plain language and require sourced answers within two minutes; misses usually signal missing capture, metadata, or note wording.
- Keep exact sensitive values in a protected store, not searchable memory; reveal them only when a task requires them and you authorize retrieval.
- Keep decisions until they are superseded, retain metrics as dated snapshots, and set expiry dates for one time logistics.
- Choose a connector that exports plain files with metadata and provenance, preserves dates and source links, and limits access; treat weaker options as convenience layers.
Table of Contents
- What is an AI second brain, and how is it different from notes or a chatbot?
- Core components and architecture: what each layer does and where to spend effort
- Quickstart: set up a working AI second brain in an afternoon
- Standards and infrastructure: MCP, memory servers, and portability
- Privacy, provenance, and user control: practical governance patterns
- Design for retrieval and maintenance: the retrieval test, retention rules, and cadence
- Example workflows: morning brief, board prep, and meeting-to-action
- Why you can trust this guide
- An editorial take: start with the manual and the test, not the tool
- How Otto fits the second brain model
- FAQ
- Sources
What is an AI second brain, and how is it different from notes or a chatbot?
A notes app stores what you put in it and waits. A chatbot answers what you ask and, in most setups, forgets the conversation when the session ends. An AI second brain closes the loop: it captures, organizes and recalls on its own, and it carries context from one session to the next. The practitioner view is a shift from “prompt-first” to “context-first” design, where the AI reads persistent context automatically and avoids the cold-start problem at the start of every session.
That shift is easy to underrate. With a prompt-first setup, you spend the opening of every conversation re-explaining who your key customers are, what you decided last week, and what you promised on Thursday’s call. With a context-first setup, that background is simply there.
Active versus passive
A passive system holds files. An active one does work with them. When a meeting ends, the active system pulls out the commitments. When a new email arrives from a customer, it can recall the last decision you made about that account. When you ask “what should I focus on today,” it has something real to answer from.
The five parts, briefly defined
- Capture: getting information in with almost no friction, from voice notes, clipped pages, email and meeting transcripts.
- Organize: storing it in formats a machine can read, such as Markdown with structured metadata.
- Recall: finding the right piece later through semantic search, with a link back to where it came from.
- Agents: repeatable routines that run against your memory, like a morning brief or a follow-up check.
- Memory: the persistent layer underneath, holding decisions, preferences and facts with timestamps.
Why persistent memory is the real difference
Files tell you what you wrote. Memory tells you what you decided and why. A folder containing forty meeting notes does not tell an assistant that you rejected a pricing change in March because of churn risk. A memory that stores that decision, with a date and a source, does. Practitioners describe successful systems as ones that focus on persistent context and retrieval-first testing rather than storing everything, and that is the dividing line between a pile of documents and a working second brain.
It also explains why plain retrieval over a document dump disappoints people. Retrieval finds text that looks similar to your question. A memory layer finds the decision, the person and the date that matter, because it was designed to hold those things as first-class items. If you remember one distinction from this section, make it that one: an AI second brain remembers decisions, not just files.
Core components and architecture: what each layer does and where to spend effort
You do not need to build all five parts at full strength on day one. You do need to understand what each does, because your effort should go where retrieval quality is decided: organization and the memory layer.
Capture: low-friction intake
Capture fails when it takes more than a few seconds. The best systems accept whatever you naturally produce: a voice memo walking to a meeting, a forwarded email, a pasted paragraph, an automatic meeting transcript. Voice is worth singling out. A phone call is one of the richest sources of commitments and one of the least captured. A voice platform such as Callspace’s conversational phone AI shows how call transcription and calendar integration can turn a spoken conversation into structured text that a memory layer can then ingest.
Everything lands first in a single inbox folder. The inbox is a holding area, not a library. You do not sort at capture time; sorting is the job of the next layer.
Organize: machine-readable and lifecycle-aware
Store things in Markdown with a little structured metadata: date, source, type, project, and status. Practitioners point to machine-readable formats like Markdown as a core trait of systems that keep working. Plain text survives tool changes, and any model can read it.
On structure, choose lifecycle over topic where you can. A topic tree (“Marketing,” “Finance,” “Hiring”) makes you decide where something belongs, and that decision is where capture habits die. A lifecycle layout asks only what stage the item is in: inbox, active memory, current projects, archive. Topics become metadata tags that search can use without forcing you to file by hand.
Recall: semantic search with provenance
Recall means asking a question in your own words and getting the relevant item, not just a keyword match. Semantic search and retrieval-augmented generation (RAG) are the standard building blocks. What separates a trustworthy system from a flashy one is provenance. Policy researchers recommend that memories carry provenance so users can see when and why a memory influenced an output, which also helps separate curated context from raw conversation history. In practice, every answer should point to the note, email or transcript it came from.
Agents: routines that run on memory
An agent here is not mysterious. It is a saved routine: “every morning, read my calendar, open commitments and unread priority email, and give me three priorities.” Other common routines are a follow-up chaser, a weekly review, and a capture command that files a thought into the right place. The value comes from repeatability. A routine that runs the same way every day gives you a baseline to improve.
The memory layer: vector index, metadata, and decay
The memory layer typically combines three things:
- A vector index for semantic similarity search.
- A metadata store holding dates, types, sources, owners and statuses, so you can filter by “recent decisions” instead of relying on similarity alone.
- Confidence and decay fields so old, unconfirmed items lose weight over time instead of competing equally with fresh, verified ones.
Research on layered personal memory points the same direction. The Second Me work describes a hybrid architecture where a personal memory provider supplies context to other models, enabling structured retrieval and context-aware actions rather than a single flat pile of text.
Timestamps and provenance are the two fields people skip and later regret. Without a date, you cannot tell a current pricing decision from a superseded one. Without a source, you cannot check a surprising answer. Add both from the start and the rest of the system gets easier to trust.
Where should your effort go first? Spend it on organization and the memory layer, not on fancy agents. A mediocre morning brief built on clean, dated, sourced memory beats a sophisticated agent running on a mess.
Quickstart: set up a working AI second brain in an afternoon
Practitioner implementations suggest that a folder, a short operating manual, a memory layer and seeded routines are often enough to produce useful output quickly, including a daily brief and first drafts. Set aside time for the setup, with the brain dump taking the longest.
- Create one root folder. Inside it, make four subfolders: inbox, memory, projects and archive. Resist adding more. Every extra folder is a decision you will have to make later.
- Write a one-page operating manual at the root. State who you are, what you are responsible for, how you like to be briefed, what the assistant may do without asking, and what it must always ask about. Include naming rules and how to mark a decision versus a note. This file is what every future session reads first.
- Do a brain dump. Write down your active decisions and the reasons behind them, the metrics you watch and their current values, your active projects with owners and next steps, key people and how you work with them, and standing preferences. Dated bullets are fine. Do not polish.
- Install a memory layer. Either set up a simple vector store with a basic RAG pipeline, or plug in an existing connector that exposes your folder as searchable memory. Point it at the root folder and let it index everything you wrote in steps two and three.
- Create three routines. A morning brief that returns your top three priorities, a capture command that drops anything into the inbox with a timestamp, and a weekly review that lists new decisions, stale items and open commitments.
- Run the two-minute retrieval test. Pick five things you know are in the system, such as last month’s pricing decision or the name of a key vendor contact. Ask for each in plain language. If a relevant answer does not surface within two minutes, the system is failing you. That threshold comes from practitioners who note that retrieval, not size, is the measure of a personal knowledge system.
- Set retention and decay rules, and book the first check. Decide how long ephemeral items live, which categories never expire, and put a maintenance slot on your calendar for next week.
Pro Tip: Seed your memory with decisions and the reasons behind them before you seed it with documents. Dated decisions with rationale will improve your first morning brief more than importing a large collection of PDFs.
A few honest expectations. Your first morning brief will be mediocre. It will miss things, and it may surface something stale. That is normal, and it is the point of the retrieval test: you find the weak spots on day one instead of discovering them during a board prep. If a retrieval fails, the fix is usually one of three things: the item was never captured, it lacks metadata, or the question uses words your note never used. Adding a short summary line and two or three tags to the note solves the third problem surprisingly often.
If you want to see how a capture-and-queue habit works once the basics are in place, our post on capturing, queuing and acting on follow-ups walks through the routine side of the setup.
Standards and infrastructure: MCP, memory servers, and portability
The question that decides whether your second brain outlives your current tools is simple: can you take it with you? That is where standards and infrastructure matter.
MCP as the portability layer
The Model Context Protocol (MCP) is an open way for AI front ends to connect to external tools and data. For a second brain, the practical meaning is this: if your memory sits behind an MCP-compatible server, several different AI interfaces can read from and write to the same memory. You can use one assistant for writing, another for coding and a third inside your chat tool, and all of them see the same decisions. Without a shared protocol, each interface keeps its own private, partial memory, and you become the integration layer again.
A common memory stack
Most working setups follow the same flow:
- Capture inbox: raw intake from voice, email, clips and transcripts.
- Vector index plus graph or metadata store: semantic search combined with structured filters and relationships between people, projects and decisions.
- Provenance logs: a record of where each memory came from and when it was used.
- Authorization layer: rules for which sensitive values can be retrieved, by whom, and when.
Hosted versus self-hosted
Hosted memory is faster to start and someone else handles uptime. Self-hosted memory, for example one backed by a SQL database such as Supabase, gives you direct ownership and easy export. Practitioner guides for founders put weight on portability and user ownership of the database. Neither choice is permanent if you keep your source material in plain Markdown, because you can rebuild an index anywhere.
If your memory also needs to feed web or CRM workflows, an automation partner such as Forefront Industries is an example of the kind of team that connects AI output to those systems.
A short connector checklist
- Does it read and write through an open protocol like MCP, or only through its own interface?
- Can you export everything, including metadata and provenance, in plain files?
- Does it preserve timestamps and source links?
- Can you restrict what it is allowed to retrieve?
- If the vendor disappeared tomorrow, could you rebuild the index from your folder?
If a connector fails two or more of these, treat it as a convenience layer, not as the home of your memory.
Privacy, provenance, and user control: practical governance patterns
A second brain holds the most sensitive material you have: contracts, compensation, health notes, customer data, half-formed opinions. Governance is not a later add-on. It is part of the design.
Principles to adopt
Three principles cover most of it. Provenance: every memory carries its source and date. Purpose limitation: a memory is used for the task it was captured for, not quietly reused everywhere. Minimal exposure by default: the assistant sees the least it needs, and exact sensitive values are revealed only when a task requires them.
The architecture pattern
Recent research on conversational agents describes a clean way to do this: separating sanitized searchable memory from a protected private store. The searchable memory holds placeholders instead of sensitive values (“the client’s account number,” not the number itself). The exact values live in a protected store and are restored only when they are relevant to the task and the user has authorized it, through authorization-gated retrieval. Mapping keys link the placeholder to the private value. The result is that everyday search and summarization never touch the raw secrets, which shrinks the damage if something leaks or an answer quotes too much.
Privacy-aware memory architectures separate sanitized searchable memory from a protected private store and restore exact private values only when they are task-relevant and user-authorized, which reduces unnecessary exposure.
User flows that build trust
User research is consistent here. Studies of how people think about RAG-based memory find that users want granular control over how memories are generated, managed and used, including review-and-commit steps and clear indications of which memories shaped an answer. Reviewers of those findings also note that the tension between personalization and privacy means practical controls and privacy-aware defaults are required for trust, not optional.
Translate that into three flows:
- Review and commit: new memories land in a pending state and become searchable only after you approve them.
- Consent for exact values: retrieving a sensitive value triggers a prompt that names the task and the value.
- Audit trail: each answer can show which memories influenced it, with dates and sources.
This is the same logic behind asking before acting. Our note on when an assistant should ask first covers how approval steps fit into everyday use.
Operational rules
- Exclusion list: define categories that never enter memory, such as passwords, full card numbers and government identifiers.
- Timed deletion: give ephemeral items an expiry date at capture.
- Review cadence: scan newly committed memories weekly and sensitive categories monthly.
- Edit and delete rights: make correcting or removing a memory a one-step action, so you actually do it.
Design for retrieval and maintenance: the retrieval test, retention rules, and cadence
The most common way a second brain fails is not a technical fault. It is hoarding. Practitioners name this as the main failure mode and recommend measuring a system by retrieval rather than by how much it stores. There is also a wider caution from business research: productivity tools can create perpetual pressure, and a memory that encourages endless accumulation without governance adds to the load instead of lifting it.
Run the loop below on a steady rhythm:
- Run the two-minute retrieval test weekly. Pick five real questions you have asked in the last week. Time how long it takes to get a relevant answer with a source. Any miss is a defect to fix, not a personal failing.
- Apply retention rules by category. Decisions are kept, with their reasoning, until explicitly superseded. Metrics are kept as dated snapshots, and only the latest plus periodic checkpoints stay active. Review preferences periodically. Set an expiry for ephemeral items such as one-off logistics, unless they are promoted.
- Keep a maintenance cadence. Daily: glance at the inbox and clear it. Weekly: triage new items, resolve conflicts and update statuses. Periodically: scan for decayed items that were never confirmed, and archive or delete them.
- When retrieval slows, diagnose before adding more. If the answer exists but does not surface, improve its metadata and add a summary line. If whole topics are thin, reseed them with a short dump. If the index is cluttered with old material, archive aggressively. Adding more notes almost never fixes slow retrieval.
Conflicting inputs deserve a rule of their own: when two memories disagree, the newer, source-linked one wins, and the older one is marked superseded rather than silently deleted. That keeps an honest history without letting stale facts steer answers.
Example workflows: morning brief, board prep, and meeting-to-action
Templates turn the architecture into daily value. Three cover most of what founders and chiefs of staff need.
Morning brief
The brief pulls from calendar, inbox and your commitments ledger, then reduces it to a short list you can act on:
- Calendar highlights: today’s meetings with a one-line context note for each, drawn from past decisions with those people.
- High-priority unread items: only messages from people or threads flagged important in your operating manual.
- Open promises: commitments you made that are due or overdue.
- Three priorities: a ranked pick, each with a one-sentence reason and a source link.
Board prep
Board prep is where a decision log earns its keep. Combine three inputs: the decision log since the last meeting, the feedback the board gave last time and what you committed to in response, and a dated metrics snapshot. The assistant drafts a first-pass narrative of what changed, what you decided and why, and which of the board’s earlier concerns remain open. You edit; you do not start from a blank page.
Meeting-to-action
The pipeline has four stages. First, the meeting is transcribed automatically. Second, the system proposes candidate actions and decisions from the transcript. Third, a human reviews them and approves, edits or rejects each one. Fourth, approved items enter the queue with owners and due dates, and follow-up reminders run until they are closed. Keeping the review step before anything is sent follows the same approval-first principle as in the governance section. For the summary side of this flow, see how meeting summaries can map notes to tasks, and for the follow-through side, how AI email drafting keeps people from switching context.

What a single shared memory changes
When email, meetings and documents write to one memory, you stop restating context. The email draft knows what you said on the call. The meeting prep knows what the customer wrote last week. If your tasks live in a separate tool, a link between them matters too; our walkthrough on how to sync tasks to Notion shows how a shared memory keeps task flow consistent with the rest of your work.
Why you can trust this guide
Every recommendation here traces back to a linked source, whether practitioner guides on retrieval-first design, policy research on provenance, or academic work on privacy-aware memory. We name what each source actually says and avoid claims beyond it.
We also build a product in this space, so you should know where we stand. Our approach is a single shared memory across email, calendar and meetings, with a human approving anything before it is sent or finalized. In terms of this guide’s architecture, that maps to the daily briefing routine, a unified ledger of commitments, and automated follow-up chasing. We welcome readers who want to test these patterns against their own workflow and tell us where they break.
An editorial take: start with the manual and the test, not the tool

Most advice about second brains begins with software: which app, which plugin, which model. I think that is backwards. The evidence in this guide points to two cheap habits that matter more than any tool choice. First, write the operating manual. It forces you to decide what the assistant may do alone and what it must ask about, and every later behavior inherits those choices. Second, run the retrieval test before you add anything else. A system you cannot query in two minutes is a filing cabinet with a chat window on top.
What is overrated is collecting. Importing years of notes feels like progress and mostly produces noise. What is underrated is deletion and decay, because a smaller memory with dated decisions beats a larger one with stale facts. If you do only one thing this week, seed ten decisions with reasons, run five retrieval questions against them, and fix whatever fails. Privacy design belongs in that first afternoon too, not after something goes wrong.
— Eddie
How Otto fits the second brain model
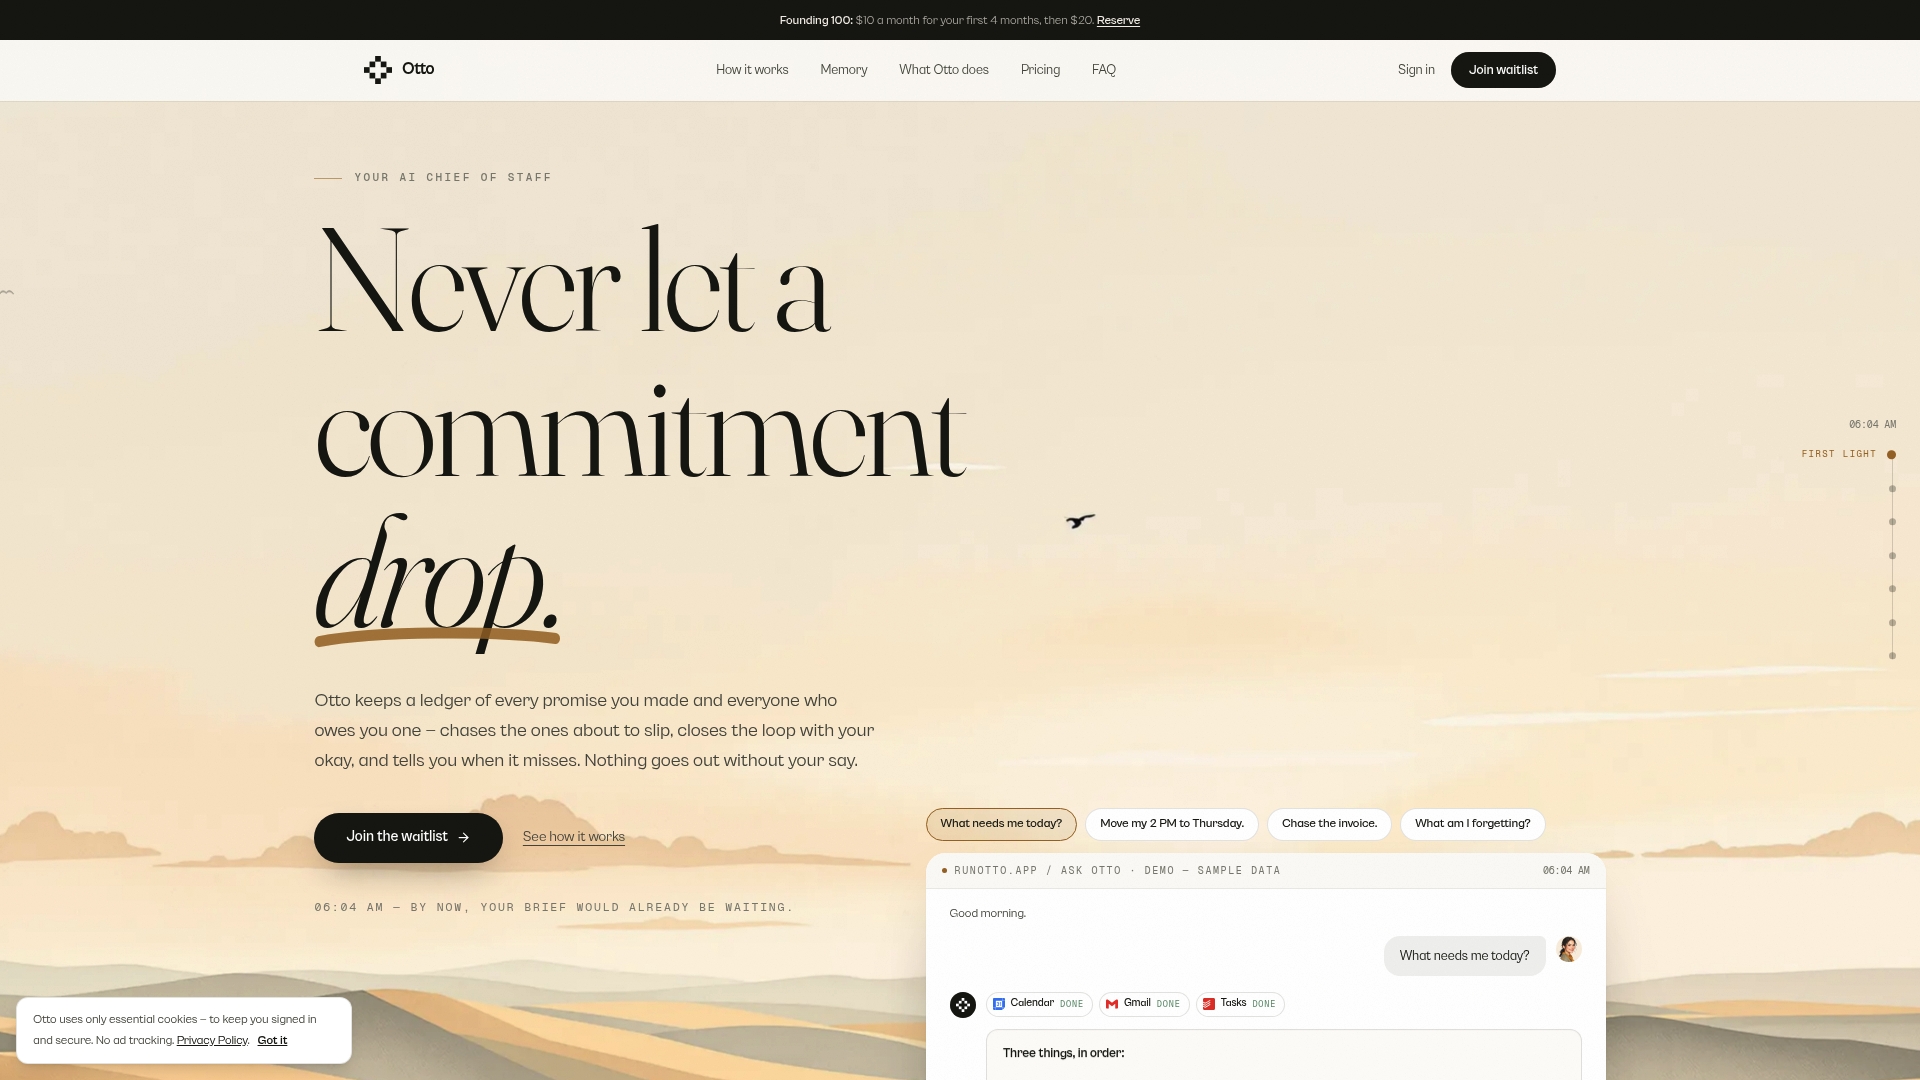
We built Otto so you never have to be the glue between your tools. It keeps one shared memory across your email, calendar and meetings, captures every promise made in any of them into a single ledger, and chases each one until it is closed. Nothing is sent or finalized without your approval: we draft, you decide. That means clearer morning priorities and fewer missed follow-ups for founders, operators and chiefs of staff whose work is scattered across many tools. You can start on our Free plan, move to Upgraded at $20 per month or Max at $50 per month when you need more. Create your account at Ottohq and ask for tomorrow’s priorities.
FAQ
What is a second brain in AI?
It is a persistent memory layer that captures your information, organizes it and recalls it across sessions. Unlike a notes app, it remembers decisions and context so an assistant can use them without being re-briefed.
What is the AI second brain skill?
It is the habit of capturing decisions and context in a form AI can read, then testing retrieval. Practitioners stress that the measure of success is whether a relevant note surfaces within two minutes, not how much you have stored.
Which AI is best for a second brain?
No single model wins on its own, because the quality comes from your memory layer and routines. Choose an interface that connects through an open protocol like MCP, so you can switch models without losing your memory.
What is the second brain theory?
It is the idea of offloading remembering to an external system so your own attention is free for thinking and deciding. With AI, that system also recalls and acts, which is why persistent, context-first design matters.
How do I keep sensitive details safe in a second brain?
Keep exact sensitive values out of searchable memory and in a protected store, restoring them only with your authorization. This separation of sanitized and private data limits unnecessary exposure.